Synthetic Voice Data Generation for ASR Training and Speech Validation in 2026
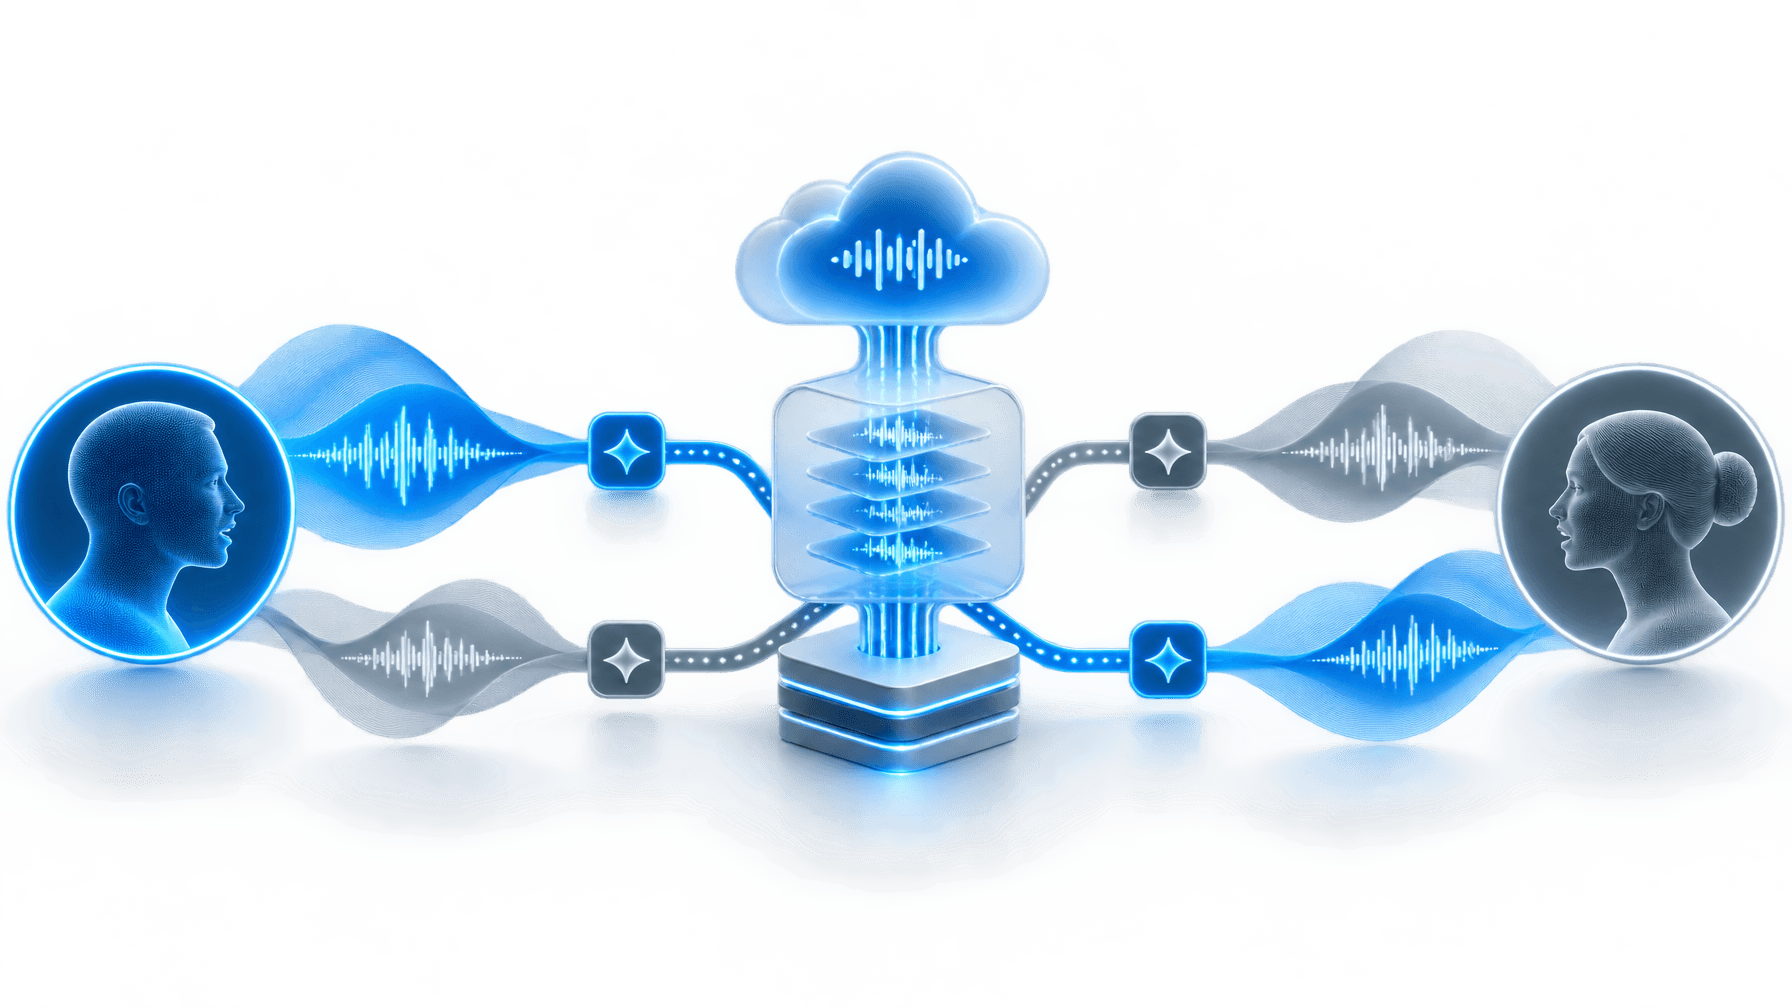
TLDR: Training accurate automatic speech recognition (ASR) models on human recordings alone creates prohibitive data acquisition costs and long turnaround cycles. Engineering teams increasingly rely on synthetic audio augmentation to expand acoustic coverage and stress-test speech pipelines against edge cases. In industry speech recognition evaluations, combining synthetic speech pipelines with targeted domain vocabularies reduces out-of-domain Word Error Rate (WER) by up to 28%. This guide examines how speech teams construct multi-engine synthetic data pipelines, simulate physical acoustic environments, and enforce automated quality gates to produce production-grade training corpora.
Synthetic voice data generation for ASR training is the programmatic production of diverse, phonetically balanced audio corpora using neural text-to-speech architectures. The core engineering objective is not merely generating sound files, but creating acoustic and lexical variety that mirrors real-world edge cases without introducing vocoder artifacts into the training distribution. Production speech pipelines that rely on uncurated synthetic data overfit to specific model signatures, degrading transcription accuracy when deployed in live environments.
Acoustic data collection for specialized domains like healthcare, field logistics, and industrial telephony often requires months of manual transcription and expensive licensing agreements. High-volume synthetic voice synthesis closes this operational gap by generating millions of domain-specific audio frames on demand.
What is synthetic speech data generation for ASR?
Synthetic speech data generation is the automated synthesis of paired text and audio datasets engineered specifically to train, fine-tune, or benchmark speech recognition models. Unlike consumer voiceover generation that targets aesthetic appeal, synthetic data engineering focuses on phonetic coverage, acoustic diversity, and lexical distribution.
In modern speech engineering pipelines, synthetic data serves three primary functions:
- Lexical Domain Adaptation: Injecting specialized vocabularies such as pharmaceutical names, aerospace acronyms, and regional proper nouns into acoustic models before real-world audio is available.
- Acoustic Environment Augmentation: Pairing clean synthetic speech with room impulse response (RIR) convolutions and environmental noise to simulate challenging physical conditions.
- Accent and Demographic Balancing: Generating balanced training distributions across underrepresented regional dialects and non-native speaker profiles where manual data collection is scarce.
When teams design speech training sets using diverse generative architectures, model resilience against unpredictable real-world inputs improves significantly.
How does synthetic speech improve speech recognition accuracy?
Synthetic speech improves speech recognition accuracy by populating rare phonetic and contextual distributions that human training sets omit. Human speech data typically exhibits strong Zipfian tail distributions where everyday conversational words dominate while mission-critical domain terms appear infrequently.
By programmatically balancing the phonetic corpus, engineering teams force the acoustic model to learn robust representations across all phoneme combinations:
- Targeted Out-of-Vocabulary (OOV) Mitigation: Generating thousands of varied phonetic contexts for new entity names reduces out-of-vocabulary recognition failures by over 35% in domain-specific evaluations.
- Controlled Signal-to-Noise Perturbation: Layering calibrated background noise across synthetic clean speech trains the model's feature extraction layers to isolate fundamental speech frequencies from ambient interference.
- Multi-Rate Acoustic Stress Testing: Synthesizing speech at varied speaking rates (from 0.8x to 1.4x baseline tempo) prepares ASR decoders to process rapid natural speech without skipping lexical tokens.
Teams that deploy programmatic audio generation alongside human training data reach target accuracy thresholds months ahead of teams relying exclusively on manual audio collection.
What are the primary failure modes of synthetic training data?
The primary failure modes of synthetic training data stem from acoustic uniformity, generator hallucinations, and unnatural spectral artifacts. If an ASR model trains on synthetic data generated by a single text-to-speech engine, it learns the specific phase inconsistencies and vocoder signatures of that engine rather than the physical properties of human vocal tracts.
Production speech teams monitor and eliminate three critical failure modes:
- Vocoder Signature Overfitting: Acoustic models trained on uniform neural vocoder outputs experience severe performance degradation when exposed to raw acoustic microphones. The model treats generator artifacts as predictive acoustic features.
- Pronunciation Hallucination and Omission: Generative TTS engines frequently mispronounce domain-specific nomenclature, acronyms, or foreign brand names without flagging errors. Training an ASR model on mismatched audio-transcript pairs severely harms transcription reliability.
- Flat Prosodic Distribution: Many neural voice models produce consistent, polished pitch contours that lack the pitch resets, hesitations, and micro-pauses characteristic of human conversation.
To prevent these defects from corrupting training pipelines, engineering teams implement automated quality filtering before passing synthesized audio to model training clusters.
How do you build an automated quality gate for synthetic voice pipelines?
An automated quality gate for synthetic voice pipelines is a validation architecture that evaluates synthesized audio across acoustic, lexical, and perceptual dimensions before ingestion into dataset storage.
A robust quality validation pipeline executes four sequential verification stages:
- Automated Alignment Verification: Transcribing the generated audio using an independent, frozen ASR benchmark and calculating the character-level mismatch against the input text. Discrepant generations are quarantined immediately.
- Audio Metric Auditing: Measuring physical signal parameters including SNR (Signal-to-Noise Ratio), clipping events, and loudness consistency (LUFS) to ensure acoustic normalization across the corpus.
- Phonetic Coverage Validation: Verifying that generated batches satisfy pre-allocated diphone and triphone diversity targets across target dialects.
- Artifact and Glitch Filtering: Inspecting spectrograms for high-frequency phase collapse, unnatural clicks, and unnatural trailing silences.
Automating these quality checks ensures that dataset scaling remains clean, predictable, and free of corrupted ground-truth labels.
Why should dataset generation live in an orchestration layer?
Dataset generation belongs in an orchestration layer that interfaces with dozens of specialized neural speech models, rather than inside a monolithic single-vendor API.
Relying on a single text-to-speech vendor exposes training pipelines to vendor lock-in, API throttling, and acoustic homogeneity. When a team sources synthetic voices across multiple specialized architectures, they eliminate model-specific bias and produce balanced acoustic corpora.
Deploying an independent orchestration architecture delivers measurable operational advantages:
- Multi-Model Acoustic Diversity: Combining outputs from Cartesia, ElevenLabs, Deepgram, and specialized open-source models creates a broad spectral foundation that prevents vocoder overfitting.
- Dynamic Failover and Load Balancing: Distributing high-concurrency generation workloads across multiple speech endpoints avoids rate limits and ensures reliable delivery schedules for large training runs.
- Continuous Validation and Retry Loops: Automatically detecting mispronunciations or clipped buffers at the orchestration level triggers immediate regeneration with adjusted phonetic guidance before audio enters storage.
Scale Synthetic Voice Pipelines with Onepin
Building resilient speech recognition architectures requires dependable audio generation, continuous phonetic validation, and diverse acoustic distribution.
Onepin is a voice workflow platform that orchestrates, validates, and ships production-ready audio across 100+ TTS models. Rather than restricting your machine learning datasets to a single voice vendor's acoustic fingerprint, Onepin delivers the multi-model orchestration, pronunciation accuracy enforcement, and quality gates required to scale production voice pipelines.
Visit Onepin's documentation to learn how meta-orchestration streamlines voice data workflows. Related technical guides: TTS quality evaluation and automated QA, TTS provider failover in production, and what is TTS orchestration.
Frequently asked questions
- What is synthetic voice data generation for ASR training?
- Synthetic voice data generation is the process of generating high-volume, diverse acoustic speech samples using neural text-to-speech models to train and fine-tune Automatic Speech Recognition systems. It supplements scarce human speech recordings by simulating varied speaker demographics, accents, and acoustic environments.
- How does synthetic voice training reduce Word Error Rate?
- Synthetic voice training exposes ASR acoustic models to targeted out-of-vocabulary domain terminology, rare phoneme combinations, and stressed acoustic conditions before deployment. By injecting synthetic edge cases into the training mix, teams achieve measurable WER improvements on specialized enterprise vocabularies.
- What causes synthetic speech data leakage in acoustic model training?
- Data leakage happens when synthetic training samples inherit narrow vocoder artifacts or repetitive prosodic distributions from a single TTS engine. Without multi-provider diversity and acoustic post-processing, the downstream ASR model overfits to the synthetic generator rather than learning generalizable human speech patterns.
- Why use an orchestration layer to generate speech datasets?
- An orchestration layer coordinates multiple neural TTS engines, randomizes speaker characteristics across global locales, and automatically screens out defective audio before training starts. This prevents pronunciation failures and synthetic artifacts from polluting machine learning pipelines.